01 / 并排看画面,逐组听声音
每组展示一次相同输入预热后的第一个正式样本。语音由 H3 与画面共同生成,未叠加 TTS、背景音乐或直播界面。
“你好,我是知微。今天陪你读书,也聊聊你的故事。”
默认只开启第一组声音。
LightX2V 原精度四步
Turbo v0.1 · BF16 DiT · 原版 VAE
MiniMax-H3 原版 50 步
无蒸馏 LoRA · BF16 DiT · 原版 VAE
上线四步配置
MXFP8 + Sage · NVFP4 VAE · 10 秒帧数适配
原始输出为 243 帧 / 10.125 秒。页面预览统一截取前 240 帧,并使用相同 H.264 CRF 16 / AAC 192 kbps 设置重新编码;没有插帧、变速或画质增强。原始文件未经重新编码,适合精细质量判断。
02 / 固定时刻的画面细节
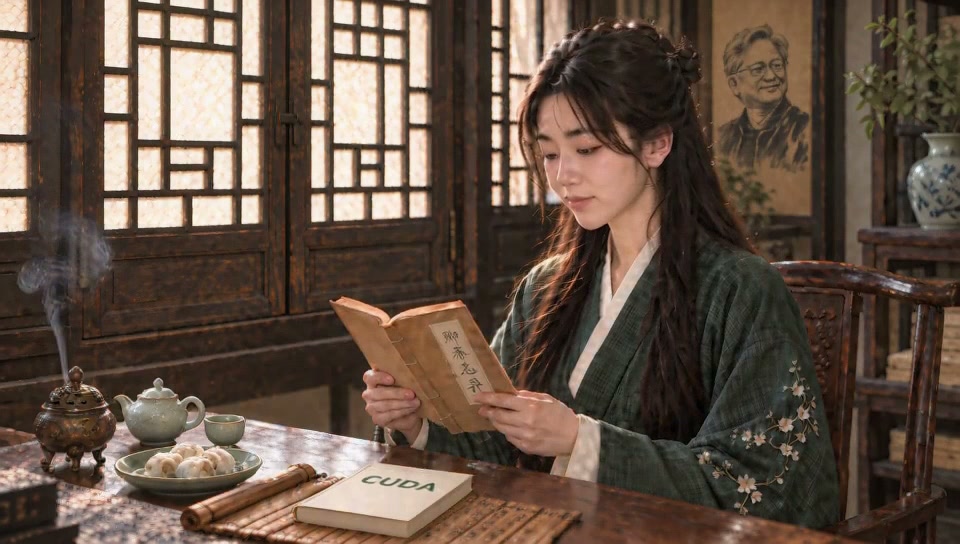
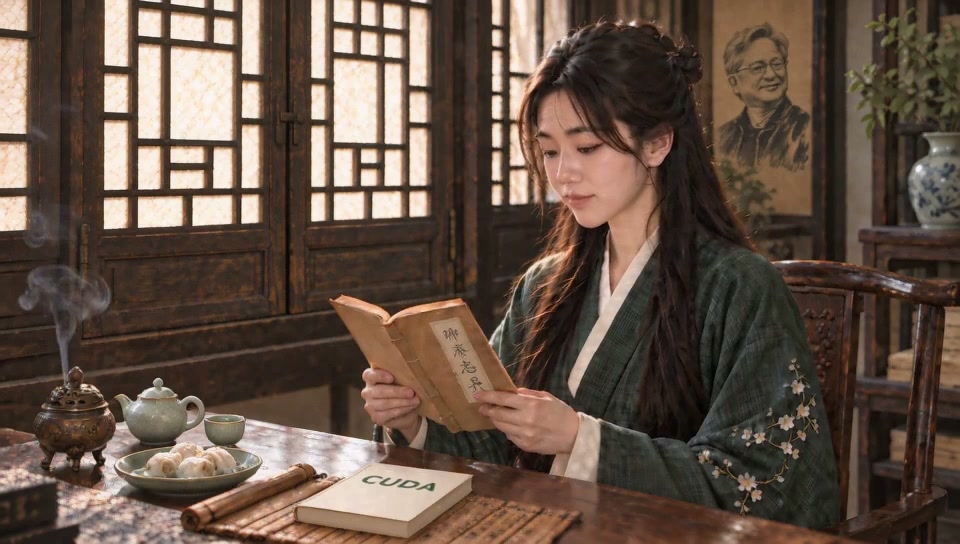
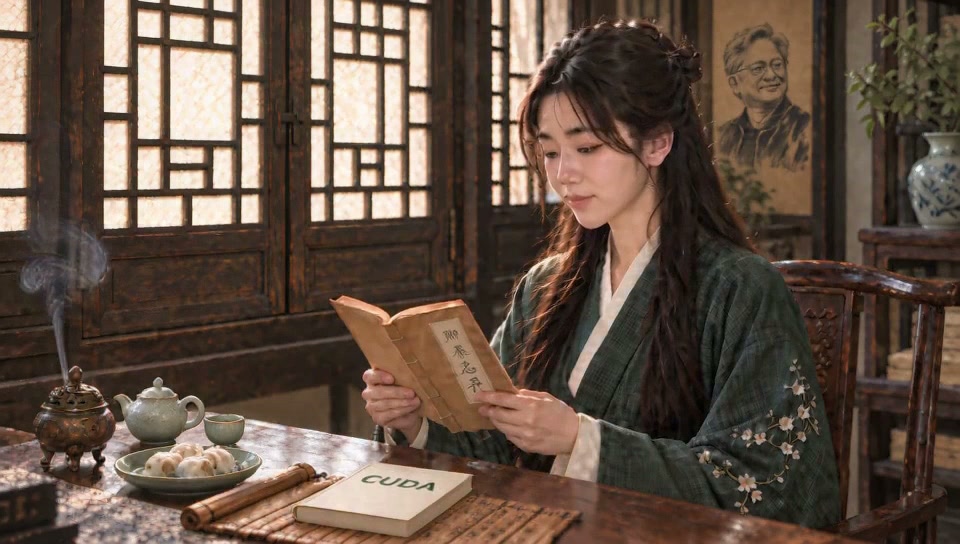
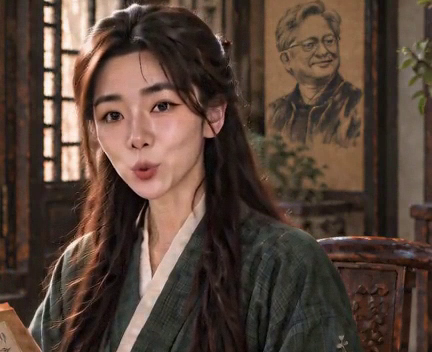
从各自原始视频提取相同时间点。面部裁切使用同一个坐标窗口,未锐化或修复;可点击查看原尺寸。
2.5 秒 · 安静阅读
7.5 秒 · 说话阶段
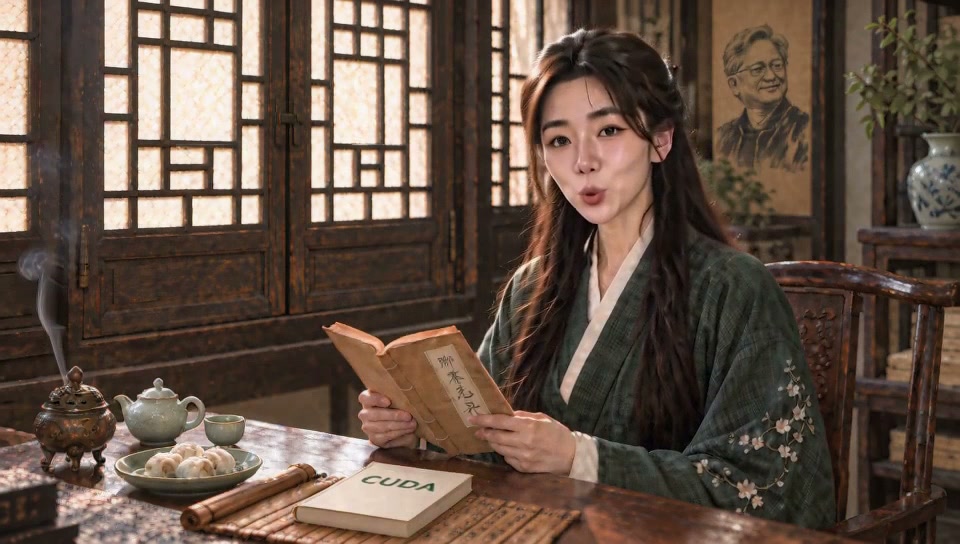
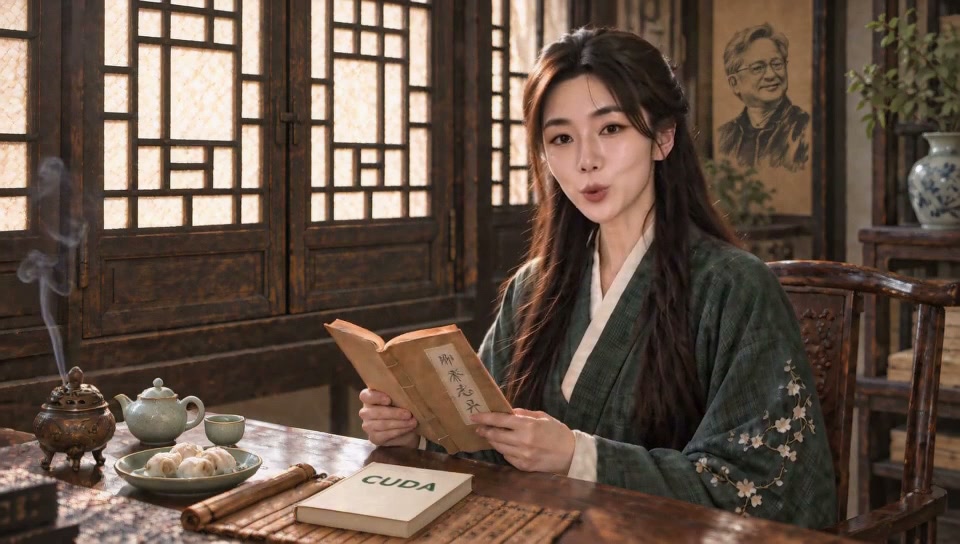
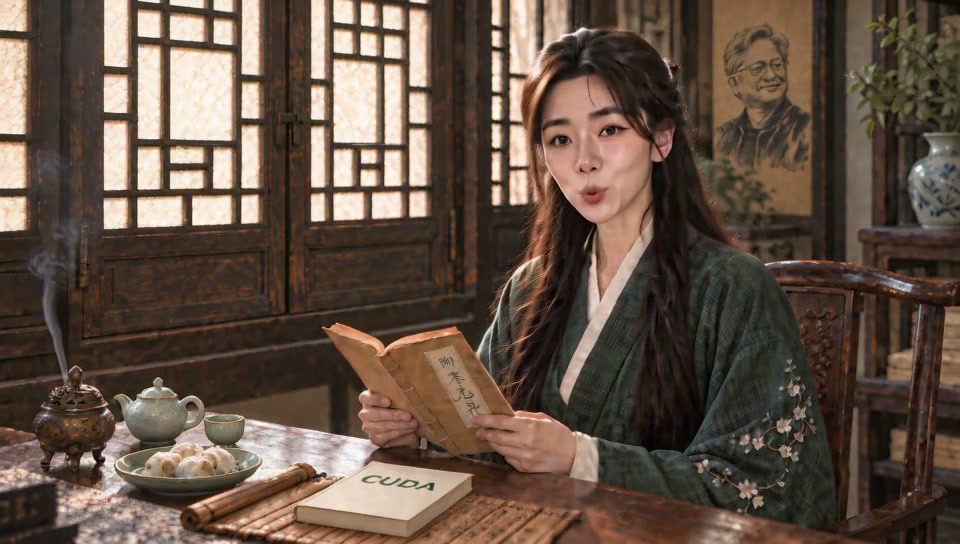
7.5 秒 · 同坐标面部裁切
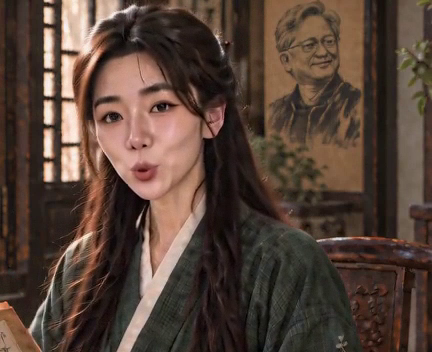
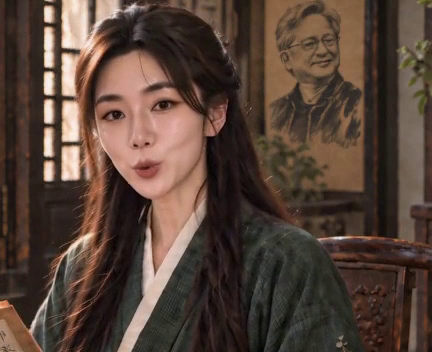
03 / 实际输出核对
| 配置 | 语音识别结果 | 说话时间 | 画面观察 |
|---|---|---|---|
| LightX2V 原精度四步 | 你好 我是芝薇 今天陪你讀書也聊聊你的故事 | ASR 估计 4.52–9.60 秒(跨度 5.08 秒) | 抽帧可见从读书转向镜头,4.5 秒时已张口;人物、衣服和桌面物件保持可辨认。说话时微笑和口部张幅较大。 |
| MiniMax-H3 原版 50 步 | 你好 我是芝薇 今天陪你读书也聊聊你的故事 | ASR 估计 4.52–9.56 秒(跨度 5.04 秒) | 抽查帧中的转头时序、构图与持书动作和原精度四步接近,未看到明显的整体质量跃升;局部细节仍需看原始视频。 |
| 上线四步配置 | 你好 我是芝薇 今天陪你讀書也聊聊你的故事 | ASR 估计 4.52–9.64 秒(跨度 5.12 秒) | 抽查帧中保持了书斋构图、持书动作和对镜头说话;面部轮廓、口部动作与发丝局部细节和原精度组有细微差别。 |
语音识别与时间戳用于核对内容和时序,不等同于人工听感、口型同步或说话人身份验收。5–10 秒是统一导演要求,实际执行情况以上表和视频为准。
04 / 配置与实验边界
| 配置 | 实际 DiT 次数 | 本次请求 → MP4 | 原始帧数 / 时长 | 完整音画解码 |
|---|---|---|---|---|
| LightX2V 原精度四步 | 4 | 24.044 s | 243 / 10.125 s | 通过 |
| MiniMax-H3 原版 50 步 | 50 | 263.845 s | 243 / 10.125 s | 通过 |
| 上线四步配置 | 4 | 6.993 s | 243 / 10.125 s | 通过 |
原精度四步:MiniMax-H3 Ref2VA 基础权重,加 LightX2V Ref2VA Turbo 4-step v0.1 LoRA。DiT 和稠密 attention 保持 BF16;完整视频 VAE 与音频 VAE 保持 FP32,无 MXFP8、Sage、NVFP4 或近似去噪缓存。
原版 50 步:同一个 MiniMax-H3 Ref2VA 基础模型,不加载蒸馏 LoRA,执行 50 次去噪。视频 / 音频 shift 均为 12 / 3,与四步输入一致。
上线四步:使用保存的上线推理源码和精度配置,四步均为 MXFP8 DiT + 稠密 Sage attention,完整视频 VAE 使用 NVFP4,音频 VAE 为 FP32。
10 秒适配:保存的上线 VAE 帧数白名单原本不支持这次单段 10 秒请求。本实验仅在独立副本中加入 72 个 latent token 的形状,沿用已有的 14 窗口解码流程,输出 243 帧;权重、量化和计算路径保持原配置,运行核验继续启用。具体单行改动与校验值见执行核验记录。
原精度组原始音轨采用 AAC 约 128 kbps、0 dB 输出增益;上线组保留 AAC 192 kbps、−3 dB 输出增益。试听响度和编码也属于这三套实际输出的差异,未进行响度归一化。
这里的“原版”指原始模型权重和推理精度;两组原精度样本通过本地 vLLM-Omni 原生实现运行,未使用上游 Diffusers 启动脚本。原精度组采用 TP8 / SP1,上线组采用 TP1 / SP8,耗时反映各自这套运行配置,不是单独量化优化的加速比。
三组都从干净参考图开始,一次生成约 10 秒,不接收弹幕、外部音频参考或上一段视频尾部。本实验观察单次生成的质量;长时间直播的续段漂移需要另外验证。50 步样本也是生成结果,不是真值视频,因此不把与它的像素相似度当作画质评分。
05 / 同一参考与完整提示词
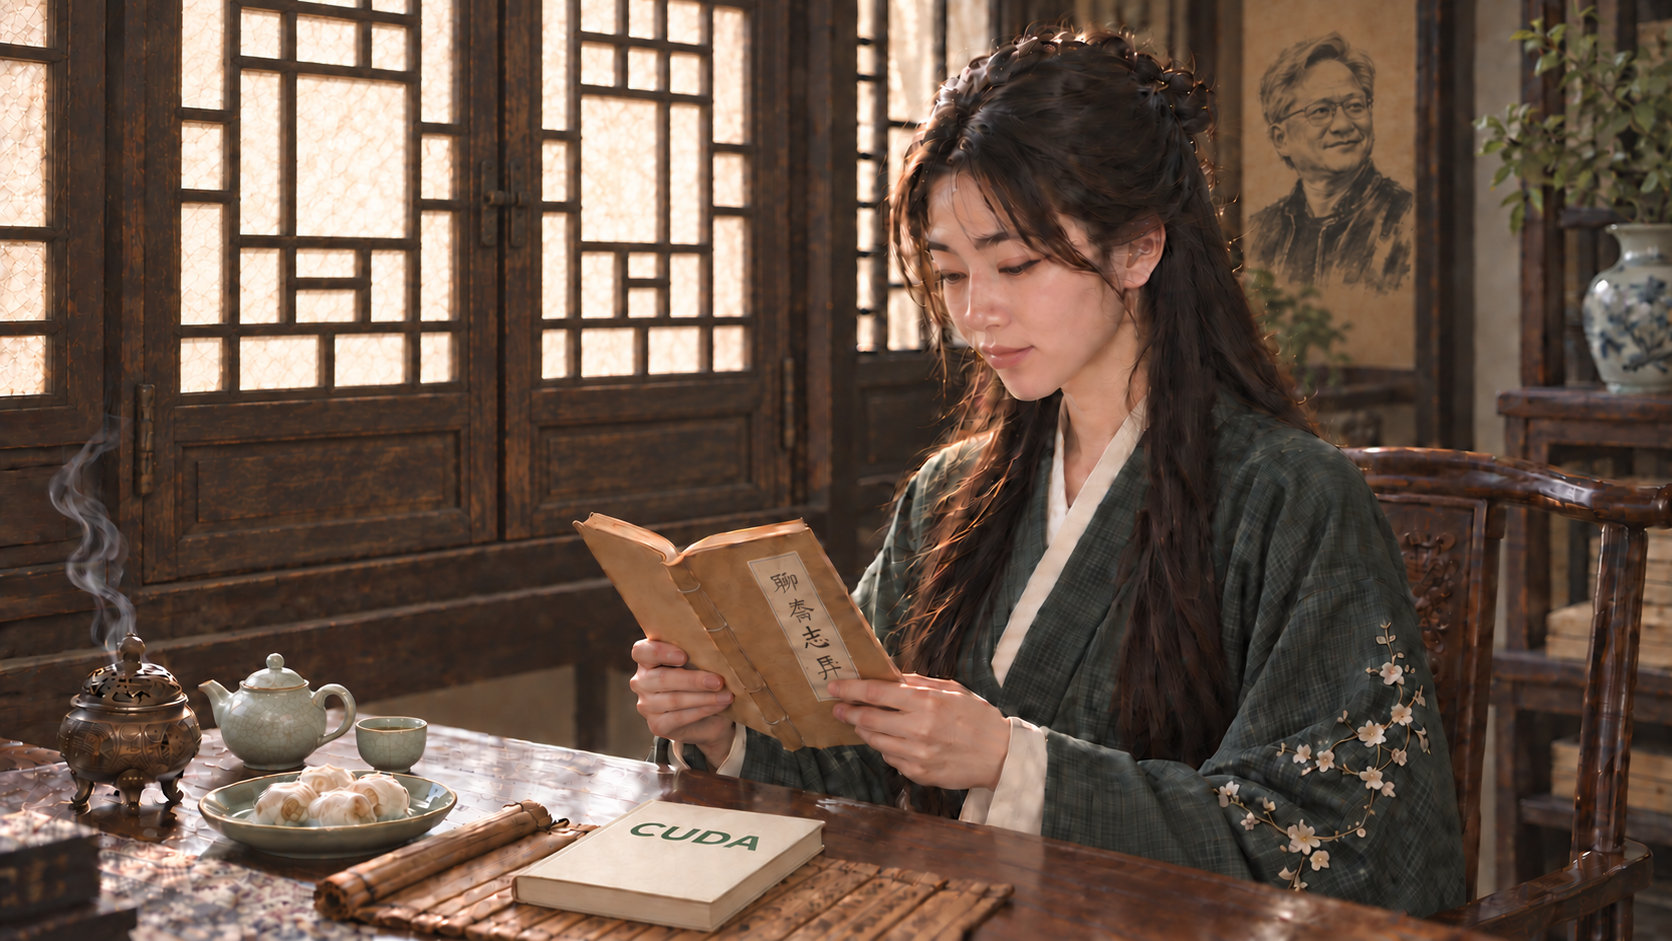
从同一张参考图开始
保留人物、服装、闭合窗户、桌面茶具、书本与光线。台词由提示词指定,环境状态在三组间相同。
上游模型:LightX2V MiniMax-H3 Turbo · MiniMax-H3。
下载原始提示词展开实际提交的完整提示词
subject_definitions:
<Subject 1> is Zhiwei, the adult East Asian woman in <Picture 1>. Preserve her face, long dark half-up hair, dark green embroidered robe with pale inner collar, and seated position. <Picture 1> also fixes the wooden study, closed lattice windows, table, book in her hands, tea set, incense burner, small plate of sweets, CUDA book and portrait scroll.

summary:
[reference generation] A single continuous ten-second photorealistic shot: Zhiwei quietly reads for the first five seconds, then looks directly into the camera and speaks to the viewer for the final five seconds.

retention_analysis:
Preserve the same woman, hairstyle, clothing, room, warm daylight and arrangement of all objects throughout. The book remains held in both hands. The windows remain closed. Camera framing stays at the reference's medium shot, with her face and hands clearly visible.

detailed_description:
Natural live-action skin texture, stable warm side light, fine hair strands, distinct embroidered fabric and coherent fingers. A completely locked camera at eye level, no cuts, zoom or camera movement.
[Shot 1, 00:00.000-00:04.300] Zhiwei sits in the same chair and reads the open book silently. Her lips stay closed. She breathes naturally and blinks once. Her hands hold the book steadily, and the tea set remains untouched.
[Shot 1, 00:04.300-00:05.000] Without moving her torso or hands, she gently raises her eyes and turns her face toward the camera, establishing direct eye contact. She remains silent until five seconds.
[Shot 1, 00:05.000-00:10.000] Keeping direct eye contact and the book in both hands, Zhiwei speaks clearly in a warm, calm adult female Mandarin voice: <d>[Chinese] 你好,我是知微。今天陪你读书,也聊聊你的故事。</d> She speaks at an even, unhurried conversational pace across these five seconds. Her mouth movements follow the actual words. She finishes the whole sentence and settles into a relaxed closed-mouth expression at the end.

overall_soundscape:
Quiet indoor room tone during the first five seconds. Only Zhiwei speaks from five to ten seconds, in clear Mandarin, with a close natural voice, synchronized lips and no singing or extra words. No second speaker or voice-over.

non_diegetic_music:
None. No subtitles, captions or added interface graphics. Keep the reference's existing book and scroll as stationary scene details.